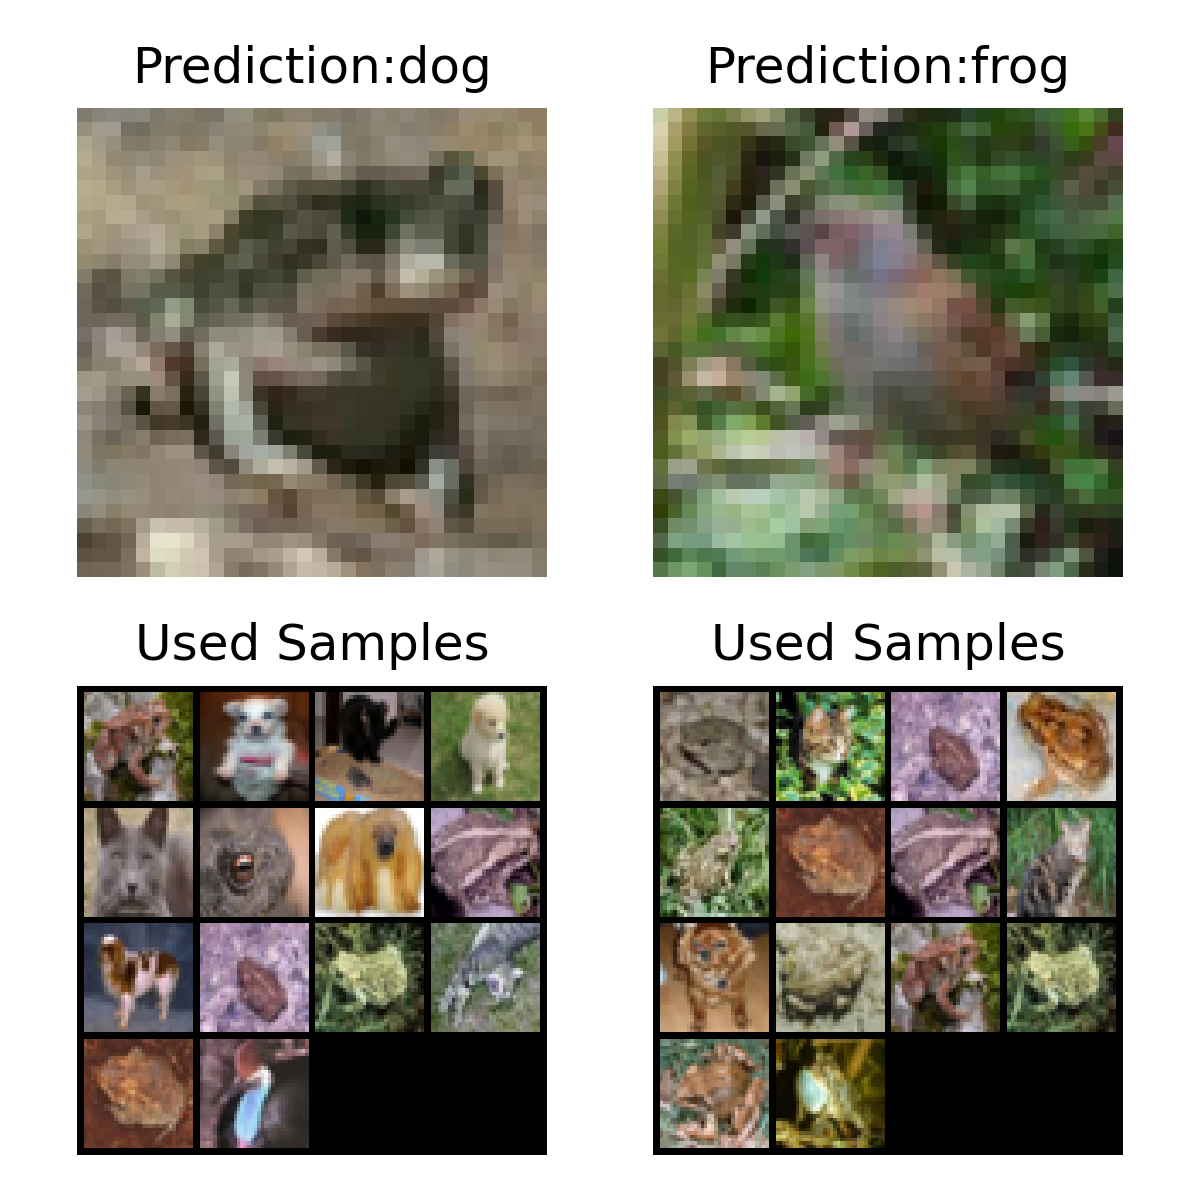
The Self-Explainable Neural Networks (SENN) group works on inherently interpretable neural networks. The explanations from these models are different from post-hoc explanations as SENNs explanations directly influence the prediction and expose the internal reasoning of the model. We currently focus on Computer Vision applications and have many ongoing projects where we are exploring how to extend SENNs to novel settings, improve their architectural designs, and training paradigms.